How to document your Kubernetes Cluster
Introduction
Kubernetes makes it easier to run and scale containerized workloads, but it can also make infrastructure documentation less straightforward. A cluster can contain many namespaces, services, nodes, pods, containers, and images, while the endpoint that provides its API may not behave like an ordinary host on the network.
JDisc Discovery can inventory configured Kubernetes clusters as part of its PaaS discovery. This article explains how to provide access, which information JDisc Discovery reads, and which permissions are needed when you also want to collect application information from containers. It complements the broader JDisc Discovery product overview, which explains how the platform inventories heterogeneous IT environments.
Why Kubernetes inventory needs a dedicated access method
Earlier JDisc Discovery versions allowed default Kubernetes access tokens to be defined and tried when a cluster was found. In practice, that is not a useful model: clusters do not normally share a token. There is another important difference from conventional network discovery. The cluster node offering the Kubernetes API must be reachable for a direct scan, but cloud installations often do not respond to ping even though the API port is open for requests.
For this reason, Kubernetes clusters are configured explicitly in the PaaS area of the discovery configuration. A PaaS discovery job then connects to the configured environments rather than relying on a ping response or a generic token.
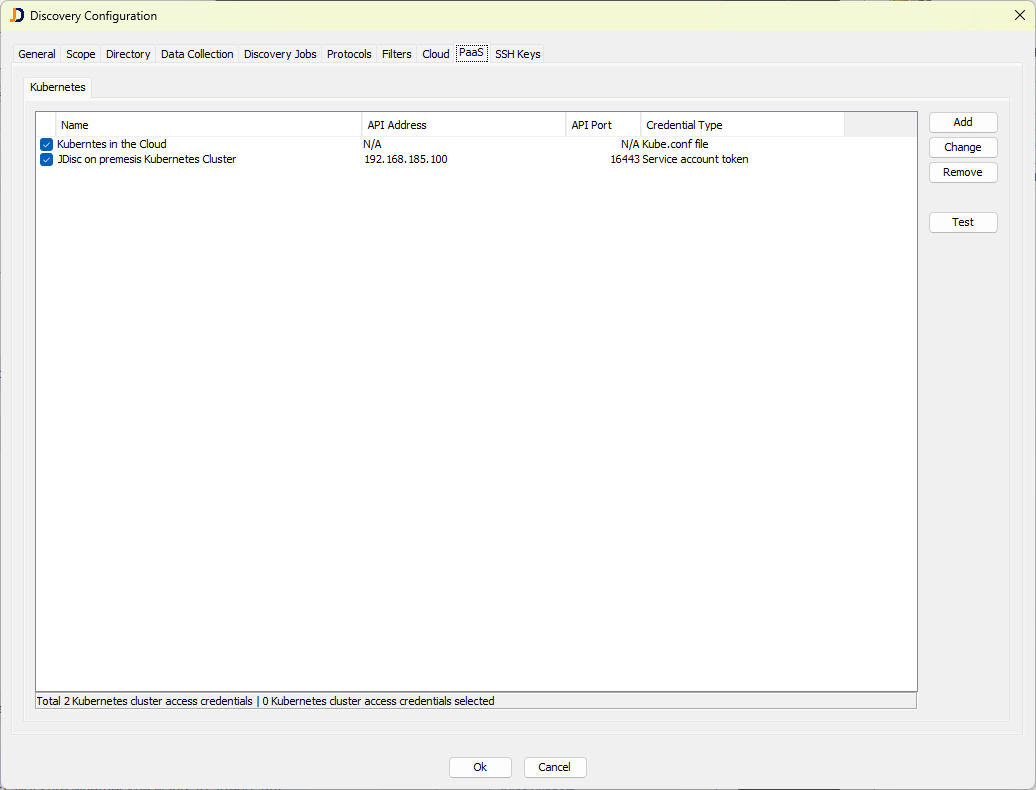
Caption: Kubernetes is configured as a PaaS entry in the JDisc Discovery discovery configuration.
Configure access to a Kubernetes cluster
There are two ways to provide JDisc Discovery with access to a Kubernetes cluster:
- A service account token
- A kube.conf file
Choose the option that fits the identity and permissions required for the information you want to collect. The access entry should use a descriptive name and comment so that administrators can identify its purpose later.
Use a service account token
Kubernetes administrators can create service accounts and long-lived access tokens for them. In JDisc Discovery, select Add to create access for a Kubernetes cluster, choose Service account token as the credential type, and enter the cluster IP address or hostname, port, and service account token.
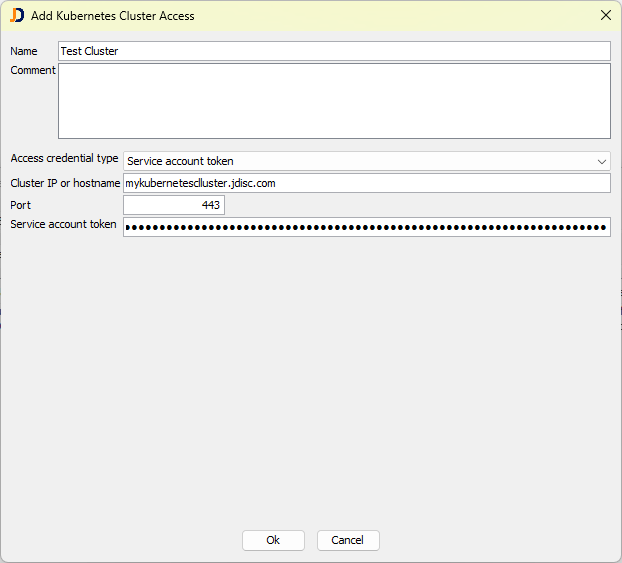
Caption: The token-based access dialog contains the cluster endpoint and the service account token.
A service account can be a practical choice when the required discovery scope is limited. Keep in mind that service accounts are scoped per namespace, so their access does not automatically extend to pods in other namespaces.
Use a kube.conf file
A kube.conf file is the second way to grant access. It contains the address, credentials, and certificates required for access to the Kubernetes cluster. This can be appropriate when the discovery needs an ordinary user and a cluster role assignment with the necessary permissions across namespaces.
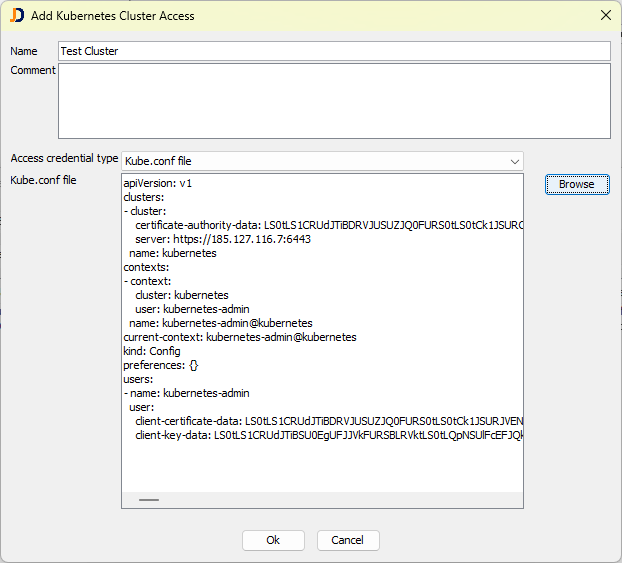
Caption: The kube.conf access option supplies the cluster connection information and credentials.
Whichever method you select, use the Test button to verify the credentials for the Kubernetes cluster before using them in a scheduled job.
Information collected from the cluster
With the necessary access, JDisc Discovery reads the following Kubernetes artifacts:
- Namespaces
- Services
- Nodes
- Pods
- Containers
- ReplicaSets
- DaemonSets
- Container images
These data points help make the structure of a configured cluster visible alongside the rest of the IT environment. They can be especially useful when a team wants to connect Kubernetes inventory with its wider device and software records. JDisc Discovery also offers optional add-ons for organizations that need to extend their discovery data with further network, security, history, or dependency information.
Required Kubernetes permissions
To read the Kubernetes artifacts above, the configured identity needs at least the following verbs:
getlist
The permissions should be granted deliberately and reviewed according to your organization’s Kubernetes access model. The scope required for inventory depends on whether the discovery should see one namespace or information across the cluster.
Collect applications inside containers
JDisc Discovery can also retrieve the list of applications running inside a container that is part of a pod. This requires the pod/exec permission because JDisc Discovery executes commands within the container.
This is where the access model becomes important. A service account is per namespace and does not have permissions for other namespaces and their pods. For pod/exec access to pods across all namespaces, use a kube.conf file with an ordinary user and an appropriate cluster role assignment that includes the required permissions.
This distinction is useful when you plan the discovery scope: basic Kubernetes inventory and application discovery inside containers may require different credentials and permissions. Treat the credentials as a managed part of your discovery configuration rather than as a default token to try against every cluster.
Create a PaaS discovery job
After configuring the cluster access, create a discovery job to run PaaS discovery for the configured Kubernetes clusters. Create the job from the context menu in the discovery job list, provide a name and description, and select the job. Do not assign a group to this job. On the Settings tab, select Synchronize PaaS as the only option.
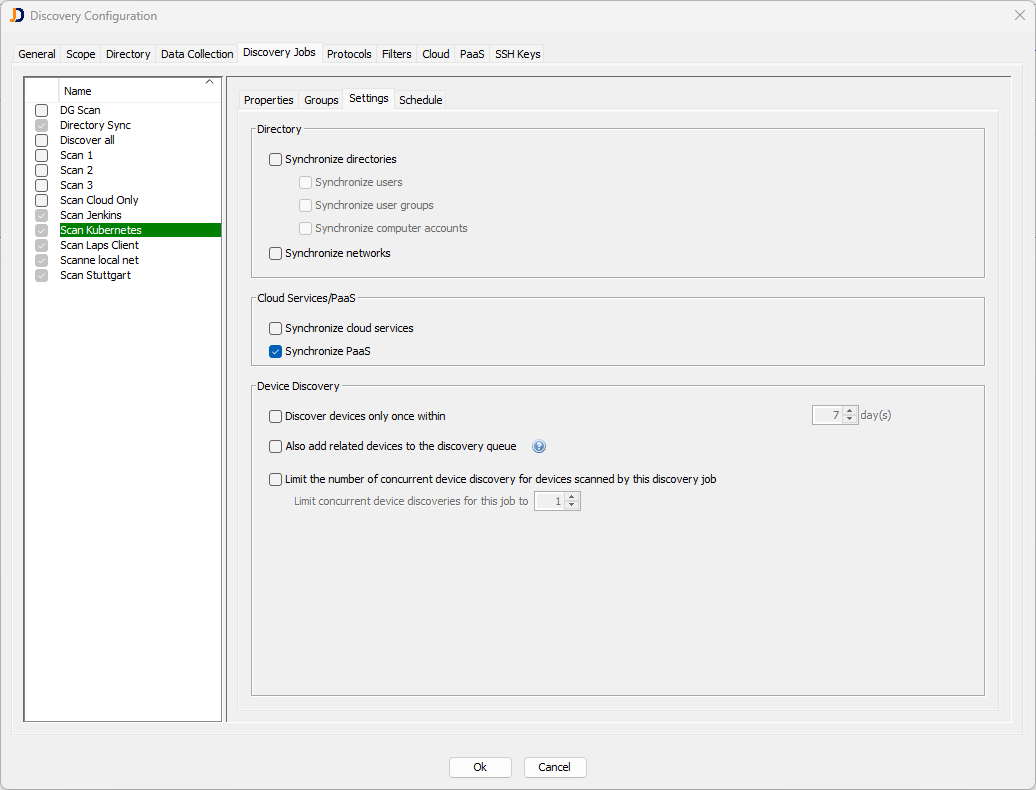
Caption: A PaaS job synchronizes the Kubernetes environments configured in JDisc Discovery.
When the job starts, it connects only to the configured PaaS entries and scans those environments. That makes the access boundary explicit and avoids treating Kubernetes as just another pingable network endpoint.
A practical way to start
Start with one cluster and an access identity limited to the information you need. Test the connection, run the PaaS job, and review the inventory result before expanding the scope. If application information from containers is needed, plan the pod/exec permission and the required cross-namespace access separately.
If you would like to evaluate this workflow in your own environment, you can download a JDisc Discovery trial or book a demo to discuss the discovery scope with us.
Frequently Asked Questions
These answers address common questions about inventorying Kubernetes clusters with JDisc Discovery. They clarify how cluster access is configured, which permissions are needed, and when a kube.conf file is the better choice.
No. Cloud installations may not reply to ping even when the Kubernetes API port is open for requests. Kubernetes clusters are configured explicitly as PaaS entries.
You can use either a service account token or a kube.conf file containing the address, credentials, and certificates needed to access the cluster.
It reads namespaces, services, nodes, pods, containers, ReplicaSets, DaemonSets, and container images when the configured access has the required permissions.
At least the get and list verbs are required to read the listed Kubernetes artifacts.
The pod/exec permission is required when you want JDisc Discovery to retrieve the list of applications running inside a container that is part of a pod.
No. Service accounts are per namespace and therefore do not automatically have permissions for other namespaces and their pods.
Use a kube.conf file when the discovery needs an ordinary user and an appropriate cluster role assignment, for example for pod/exec access across pods in all namespaces.
Create a discovery job with Synchronize PaaS as its only setting. The job then connects to the configured PaaS entries and scans those environments.
About The Author